Noisy Neighbor Query Isolation in Shared OLAP Cache Environments
Shared OLAP caches need tenant isolation beyond query rate limits.
Noisy neighbor query isolation in shared OLAP cache environments is a cache architecture problem. Preventing one tenant from degrading another’s queries requires tenant-keyed cache namespacing, per-tenant memory budgets, and query scheduling operating together. Those controls also need tenant-level observability so operators can explain latency changes and calibrate isolation against real resource use.
Why QPS caps fail as the primary isolation mechanism in shared OLAP cache
Consider two workloads sharing an OLAP cache. One begins issuing more complex queries, and both workloads spike to multi-second p95 latencies, even though the second workload’s traffic pattern has not changed. Yet aggregate request rates and p50 latency can still look normal, so standard monitoring may not show why the slowdown happened. The resources consumed per query changed.
Why would a QPS cap miss that change? A single high-cardinality join and a microsecond aggregation both count as one query to a rate limiter, despite consuming orders-of-magnitude different cache and CPU resources. Per-query cost is heavy-tailed rather than uniform, so request count is a poor proxy for the pressure a workload creates. A tenant can stay within its rate allowance while consuming resources that its neighbors depend on. By the time tail latency exposes the problem, the shared resource has already been consumed.
Counting admissions cannot account for the memory pressure, cache displacement, or CPU consumption that an admitted query will generate. QPS limits may constrain request volume, but that is not the same as isolating workloads. Isolation needs units that measure how much of each resource a query uses, including cache memory, CPU time, and scan bytes.
How cache eviction is the primary propagation path for noisy neighbor interference
Cache eviction explains how an unchanged workload becomes a victim. In a shared cache without tenant-keyed isolation, one tenant’s hot data can displace another tenant’s warm data. Subsequent queries that need the displaced data must refetch it. The victim’s query pattern can remain exactly the same. What changed was the residency of the data those queries relied on, through pressure generated elsewhere in the pool.
When warm data is backed by remote object storage, eviction-driven refetches add both latency and retrieval cost. An S3-backed refetch is a storage expense that follows from how the architecture handles displacement. A noisy neighbor can make another tenant’s unchanged workload slower and more expensive at the same time. This is why the read path after an eviction deserves as much attention as the read path on a cache hit.
The damage can spread beyond the first victim. Slower queries hold compute resources longer, increasing contention for the next tenant in line and turning one eviction event into a cascade. Aggregate latency shows what happened but not who first put pressure on the pool. Without tenant-prefixed cache keys, operators cannot tell which tenant put that pressure on the cache. Tenant-keyed namespacing is therefore a prerequisite for downstream isolation controls to work.
Tenant-keyed cache namespacing as the prerequisite isolation layer
Cache keys must encode tenant identity so that cached data belongs to a distinguishable tenant namespace. That creates the boundary against which residency controls can operate. It is not, by itself, a memory allowance. Rather, it makes it possible to distinguish one tenant’s footprint from another’s and enforce policies that stop activity in one namespace from displacing protected data in another. Without that distinction, the cache remains an undifferentiated pool.
This boundary is different from data access control. Row-level security can prevent a tenant from reading another tenant’s records while leaving both tenants exposed to contention in shared compute and cache resources. A tenant can be perfectly isolated at the data layer and still evict a neighbor’s cache lines. Logical data isolation and compute isolation are separate decisions.
Tenant identity also makes cache behavior attributable. Once entries are tenant-keyed, operators can observe per-tenant hit rates, eviction pressure, and working-set size directly. Those signals provide the basis for memory budgets and help explain latency that a CPU scheduler alone cannot account for. A tenant staying within its CPU budget does not prove that its cache footprint is harmless.
Per-tenant memory budget enforcement at the cache layer
Per-tenant memory budgets turn a named footprint into a bounded one. Enforcement must track actual bytes held in the cache pool for each tenant, because the purpose is to constrain the eviction pressure that tenant can create. Query count cannot express that footprint. Once a tenant’s cache use is bounded, expensive queries cannot simply claim an ever-larger share of the pool at the expense of neighboring workloads.
Soft quotas should precede hard limits as a design principle. A tenant that occasionally exceeds its budget during a low-contention period should be able to use spare capacity. Otherwise, strict partitioning would give up the statistical multiplexing benefit that justified sharing the pool. Hard enforcement is needed when pressure on the pool as a whole would cause cross-tenant eviction.
QWI provides workload-level CPU and memory budgeting across broker and server tiers. Each broker and server uses its own cached budgets to decide what to enforce without asking a centralized coordinator, so enforcement cost does not grow with cluster size. That is a concrete case for host-local enforcement. It supports the resource-budgeting principle, but it does not establish that workload memory accounting alone implements tenant-keyed cache residency protection.
Query scheduling and admission control as the third isolation layer
A limit on a tenant’s cache footprint does not set aside CPU or concurrency slots for it. A tenant that runs high-cost concurrent queries can still use up those resources and make other tenants wait while staying within its cache allowance. This interference bypasses the cache boundary entirely. Query scheduling and admission control must control which work enters the shared compute pool.
The decision to admit a query needs to take its projected query cost into account. A query scanning hundreds of millions of rows and running a high-cardinality aggregation should not receive the same weight as a point lookup. Interactive dashboard queries receive priority, while expensive batch or exploratory queries enter when capacity exists. Under pressure, the lower-priority work waits longer in the queue.
All three layers must operate at once. Budget enforcement without scheduling can admit enough expensive work for a tenant to exhaust its CPU allowance before enforcement intervenes. Without tenant-keyed cache protection, scheduling can admit queries fairly even as those queries change the cache in ways that harm other tenants. Memory budgets address footprint, while scheduling addresses access to compute and concurrency.
The case for physical isolation and why it fails under real traffic patterns
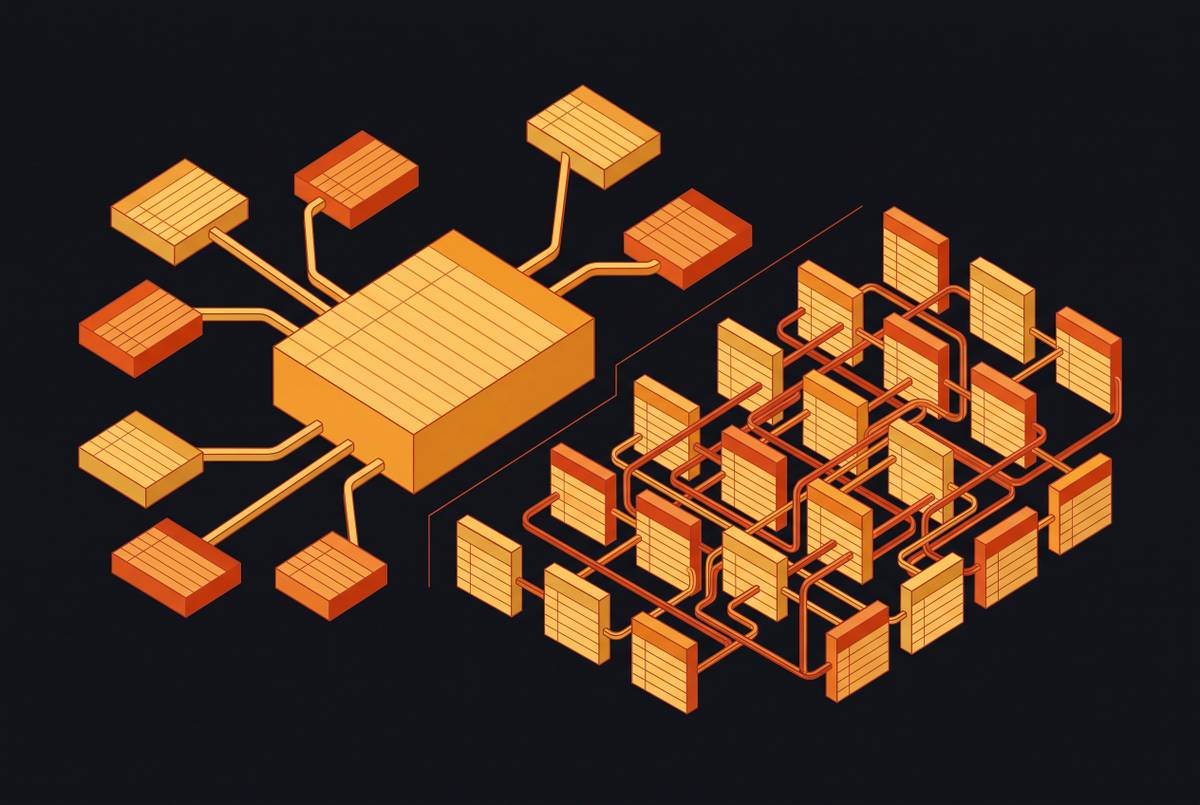
Dedicated per-tenant compute is another way to avoid having to coordinate these controls. Cache namespacing, memory budgets, and scheduling must work together, and each control adds a risk when running the system. Why take on those moving parts if tenants can run apart? For high-value, compliance-driven tenants, dedicated resources are a valid choice because they provide hard resource isolation and remove cross-tenant contention within that dedicated boundary.
The difficulty appears at the fleet level. OLAP traffic is bursty and diurnal, so a cluster sized for one tenant’s peak is over-provisioned during its quieter hours. One-cluster-per-workload also means ingestion must be duplicated across silos. Operational cost then scales with tenant count independently of actual utilization. The economics of that arrangement hold for only a small fraction of a SaaS customer base, even when the isolation itself is attractive.
Shared compute exchanges that idle capacity for governance complexity. A clean data model does not prevent noisy neighbors, and workload management, admission control, caching, and pre-aggregation all add design work. Per-tenant physical compute should be used for hard compliance requirements or extreme workload asymmetry, and layered isolation for the rest of the fleet. Within the shared pool, soft quotas and weighted fairness need calibration by tenant class so that efficiency does not come at the expense of predictable service.
How AI agents introduce a qualitatively different noisy neighbor pattern in shared OLAP caches
AI agents make the same isolation problem harder because their query pattern differs from that of a human analyst. Instead of issuing one deliberate query, an agent can generate exploratory, multi-step, and often redundant queries in rapid succession. There may be no human checkpoint between them. A runaway session can fill a tenant’s memory budget, consume concurrency slots, and, without effective protection, drive eviction across co-located tenants before anyone notices the session is active.
The sequence is therefore the unit of concern. A series of admissions can create pressure across cache memory and compute even when no single request explains the whole event. A 2025 paper on MCP privilege management identifies uncontrolled API usage and gaps in per-tool quota enforcement as a security risk. That finding concerns MCP ecosystems. Its relevance here is the identified quota gap around autonomous tool use, which makes explicit resource boundaries more than a precaution against hypothetical behavior.
Agent sessions also require isolated, read-only compute over shared data. Read-only access addresses the risk of writes, but it does not stop an agent from interfering with production queries when both use the same compute pool without a boundary. Correctness, governance, and resource isolation are separate concerns. Full query logging per agent session is the minimum accountability layer, because operators need to reconstruct which agent query caused which eviction event. Autonomy does not remove the need for attribution.
Observability that makes the three isolation layers operable in production
Request rate, latency percentiles, and CPU utilization show symptoms without exposing the full causal chain. Operators may see a victim’s latency spike without seeing which tenant caused the cache displacement or CPU contention. Isolation observability therefore needs the same tenant boundary as isolation enforcement, rather than a separate view that treats the pool as one workload.
Per-tenant cache hit rate, eviction pressure, and working-set size provide the signals needed to calibrate memory budgets. A falling hit rate means something different when it follows another tenant’s eviction pressure than when it reflects the tenant’s own changing working set. Tenant-level traces make that distinction investigable. Without them, operators are adjusting allowances blindly, unable to connect a budget decision to the residency and latency it was meant to protect.
Agent workloads require a wider view of causality. Observability must capture the query sequence, arguments, and intermediate results. The interference may be distributed across a multi-step reasoning chain that no single span records. Per-session query logging and per-tenant eviction traces together provide the accountability needed to connect autonomous activity with its effects on the shared pool.
The operational test is whether a team can explain a customer’s degraded latency and show which boundary failed or held. Cache namespacing, memory budgets, and query scheduling without the observability to verify them leave that question unanswered. A team deploying those controls alone has built isolation it cannot calibrate, audit, or defend to the customer whose queries slowed down.