Foreign Function Interface in Analytical Database Engines
Query planners go blind when foreign functions enter analytical database plans.
Foreign Function Interface in an analytical database is the point where two execution models that were never designed to cooperate collide: the declarative, set-oriented evaluation that SQL depends on, and the procedural, record-at-a-time execution that foreign language runtimes assume. SQL evaluation hands the engine control over order, parallelism, and data movement. The moment a query calls out to a foreign function, control passes to code that makes none of those assumptions. Research on optimizing UDF queries in SQL data engines treats this impedance mismatch as a core bottleneck in UDF performance, not a side effect of poor implementation. Every design decision that follows, memory ownership, type coercion, vectorization, query plan visibility, traces back to how an engine chose to resolve that mismatch rather than to which foreign language it happens to call.
Why the query planner loses visibility when a foreign function enters the plan
A query planner's job is to estimate cost and reorder operations so the engine does the least work possible. A foreign function gives it nothing to estimate. The planner has no way to know what the function does internally, so it treats the call as a fixed-cost atom no matter what actually happens inside it. This isn't a flaw in any particular planner's design. It follows directly from FFI itself, because the foreign runtime's execution behavior is opaque to the SQL engine's cost model by definition. The EDBT 2026 paper on UDF query optimization names this as the central problem: planners treat UDFs as black boxes, and that opacity forecloses the reorderings and fusions that make analytical queries fast.
Think through what that costs in practice. If a UDF is expensive and selective, placing it late in the plan wastes work computing it on rows that an earlier filter would have dropped. If a UDF is cheap and non-selective, placing it early wastes the overhead of crossing the language boundary on rows the next operator would have discarded anyway. A planner with no visibility into the function cannot tell these two cases apart, so it cannot make the right call either way.
GRACEFUL, a learned cost estimator for UDFs presented at ICDE 2025 by researchers at TU Darmstadt, takes this blindness on directly. It builds a cost model that can see into foreign function execution and feeds those estimates back to the query planner. A dedicated research effort aimed at fixing optimizer blindness says something about how consequential that blindness has become.
Vectorized execution and scalar foreign calls
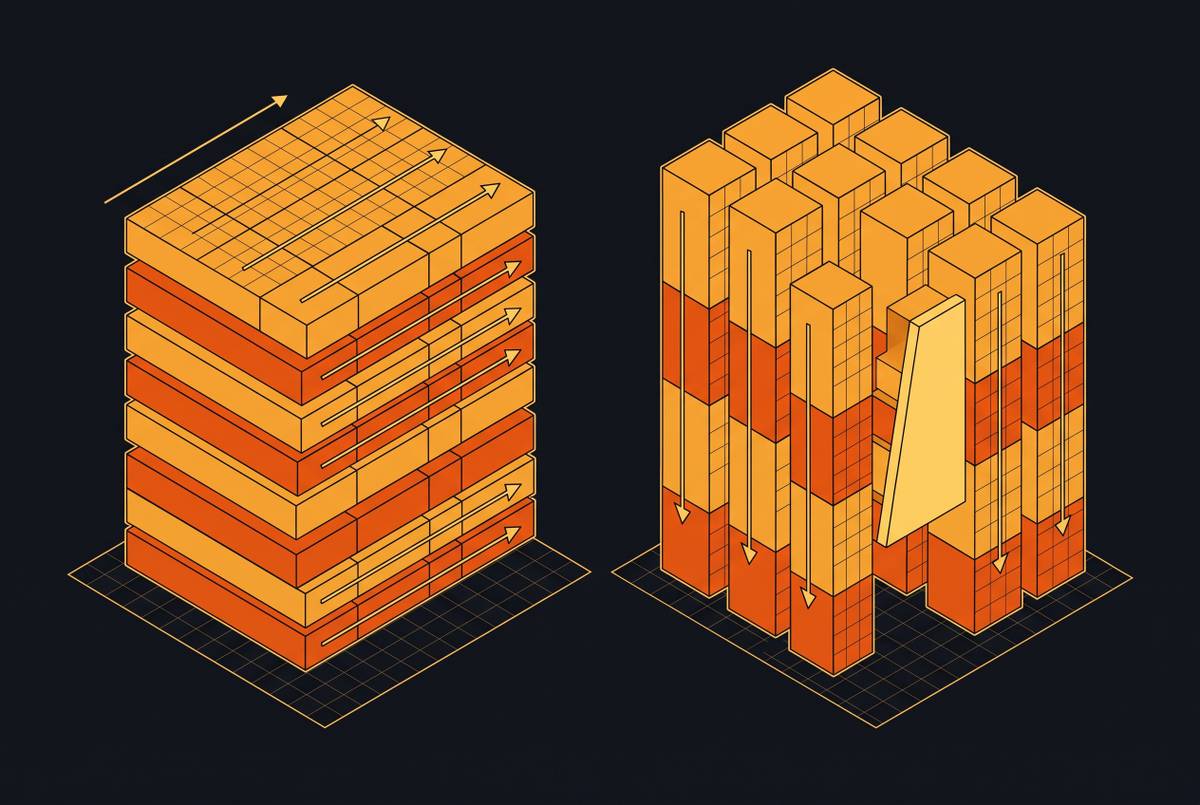
Analytical engines get their speed from vectorized execution: processing data in columnar batches that move through the pipeline together. A scalar FFI call breaks that pattern at the exact point it's invoked. The engine either drops vectorization for that stage of the query or builds costly wrapping infrastructure to work around the interruption.
Every foreign call carries its own tax: crossing the language boundary, marshaling arguments into a format the foreign code understands, and converting the result back. Pay that tax once per batch and it's manageable. Pay it once per row, and the overhead compounds across the entire relation. Python UDFs show this most clearly. Converting between Python objects and the C or C++ memory layouts that most analytical engines use internally has to happen at every boundary crossing, and Python's global interpreter lock limits the parallelism that columnar engines are built around.
That's the problem operator fusion exists to solve. The EDBT 2026 paper describes fusion, combined with inlining, vectorization, parallelization, and stateful JIT-compiled execution, as a set of techniques that together cut UDF execution overhead and restore compatibility with vectorized pipelines. QFusor, the pluggable optimizer the paper introduces, applies these techniques across SQLite, DuckDB, MonetDB, PostgreSQL, PySpark, and a commercial database. The mechanism behind it: inlining the UDF's body directly into the query's execution pipeline, instead of calling out to it, lets JIT compilation see across what used to be a hard boundary. From there it can apply vectorization, loop unrolling, and register allocation to the foreign code as if it had been native all along.
The type system gap that every FFI layer must either solve or paper over
SQL's type system and any foreign language's type system were built independently, by people solving different problems, and they do not line up. Every FFI layer has to define its own rules for converting one into the other, and those rules run into limits that no amount of engineering removes. SQL carries nullable set semantics, precise decimal arithmetic, and composite structured types. A language like JavaScript has no direct equivalent for OUT parameters, record types, nested tables, or associative arrays. These are genuine semantic gaps between two type systems, not bugs waiting on a patch.
PL/SQL record types, nested table types, associative arrays, vector types, and abstract data types do not cross the FFI boundary. This comes from a mature, production enterprise FFI, not an early prototype, and it shows that even a heavily resourced implementation leaves large parts of the type system stranded on one side of the line. The same documentation shows the workaround Oracle built for OUT and IN-OUT parameters: since JavaScript has no concept matching them, the FFI introduces wrapper objects, arg() and argOf(), that simulate reference semantics. Every caller sees that seam.
The pattern holds wherever two type systems diverge. The FFI layer restricts what can cross the boundary, wraps data in objects that expose the mismatch to the programmer, or quietly coerces values in ways that change precision or nullability. That last failure mode is the most dangerous of the three, because it doesn't fail loudly. It just changes the answer.
Why benchmarks did not measure UDF performance before 2025
UDFs have been running in production analytical systems for years. The benchmarks used to compare those systems, the ones vendors and researchers relied on to make purchasing and architecture decisions, did not test UDF-heavy workloads. That left FFI overhead invisible in the numbers that mattered most.
UDFBench closed that gap. Developed by researchers at Athena Research Center, with one author also affiliated with the University of Athens, it won the VLDB 2025 Best Experiment, Analysis & Benchmark Paper Award at the VLDB conference in London, held September 1 to 5, 2025. UDFBench is a UDF-centric benchmark built on real-world schema and data, the OpenAIRE Graph Dataset, and it's designed to isolate specific overheads: invocation cost, type conversion, and parallelism loss, measured individually and in combination. That kind of isolation is what honest comparison across engines actually requires.
The recognition from VLDB matters because it signals that the research community, not just one team, agreed this measurement gap was worth closing. Before UDFBench, an engine could post strong numbers on TPC-H or TPC-DS while performing poorly on the UDF-heavy workloads that data science and analytics teams run every day. The performance gap existed. Standard evaluation simply couldn't see it.
The security and isolation trade-off that shapes which FFI architectures work in multi-tenant deployments
Operator fusion and JIT-level inlining fix the vectorization slowdown caused by crossing the boundary between the SQL engine and the foreign function by collapsing that boundary. That same collapse removes the isolation that protects the engine's own memory and, in a shared environment, protects other tenants' data too.
This is a real trade-off, not a problem waiting on a clever fix. The techniques that make FFI fast, inlining, shared memory, are the same techniques that make it dangerous once multiple tenants share the same engine. One might argue that performance should win in a single-tenant deployment and safety should win in a shared one, and the research bears that out: there is no single architecture that maximizes both at once.
WebAssembly offers a different point on that spectrum. A Wasm runtime enforces memory isolation by construction, limits what a foreign function can do to the host, and travels with the engine, independent of any particular server. In exchange, it gives up some performance for a hard isolation guarantee. Research on automating database-native function synthesis with large language models takes a different route to the same trade-off: if the model generates native SQL or engine-specific dialect code instead of crossing an FFI boundary at runtime, there's no boundary left to isolate and no foreign runtime to constrain. The security surface shrinks because the FFI itself disappears.
But that approach has a cost of its own. FFI gives analytical engines access to libraries, numerical computing packages, Rust machine learning crates, statistical frameworks, that carry decades of engineering no synthesis model can replicate on demand. Trading FFI away for safety means trading away that ecosystem too.
Formal verification and FFI correctness requirements for engine implementers
Even a carefully engineered FFI that avoids obvious memory bugs and type coercion errors can still produce wrong answers, if the semantic contract between the SQL engine and the foreign runtime was never formally specified. Informal agreements between two execution environments are exactly where subtle, hard-to-reproduce bugs come from.
VeriFFI, work on a verified FFI between Coq and C from Princeton, Heriot-Watt University, and Bloomberg L.P., gives this problem formal grounding. It establishes that correctness at an FFI boundary requires explicit reasoning about memory ownership, representation invariants, and the line between a verified world (the engine) and an unverified one (the foreign code). The foreign function doesn't just return a value. It operates in a different memory model entirely, and any assumption the engine makes about memory state after that call is a potential source of wrong results unless the contract spells it out.
For analytical engines, that has a direct practical consequence: sandboxing through Wasm or process isolation is also a correctness strategy, because it replaces an informal, unverified memory contract with a boundary the runtime enforces, beyond the performance concession it pays for safety.
How agentic workloads change the FFI problem
When AI agents, rather than human developers, start writing and calling UDFs, the FFI surface doesn't just get bigger. It changes shape. Agents generate foreign function calls programmatically, often in parallel, against schemas they're still exploring rather than ones they already know, and at rates that expose performance and safety problems no human-paced workflow ever triggered.
That compounds the optimizer blindness described earlier. Agents probing an unfamiliar schema tend to pull in irrelevant schema elements as they explore, and when those exploratory queries include foreign function calls, the planner's inability to see inside those calls makes the resulting plan worse than the over-exploration alone would have caused.
Agentic access also demands something current FFI APIs were never built to provide: machine-legible contracts. An agent deciding whether to call a UDF needs to know what it accepts, what it returns, and what it costs, before making that call, not after. And because an agent can issue calls autonomously, every invocation needs to be logged with enough context to reconstruct what the agent was doing and why. Autonomous doesn't mean unaccountable.
Sandboxed, read-only compute environments, where agents work over shared data without touching production state, line up directly with the isolation architecture that Wasm and process-boundary approaches already support for performance and safety reasons. The engineering investment in isolation ends up paying off twice: once for multi-tenant safety, once for agentic access control.
Where FFI responsibility should live in multi-model engine design
An engine built to serve more than one data model, relational, document, graph, has to resolve the FFI mismatch at every model boundary it supports, not just once at the edge of the system. Where it lands architecturally reveals whether it treats FFI as a concern for the query layer, the storage layer, or a dedicated runtime of its own.
M2, an analytic system built with specialized storage engines for multi-model workloads, takes the position that different data models need different storage and execution strategies. That implies FFI boundaries aren't uniform across such an engine and can't be resolved with one single approach applied everywhere.
That leaves engine designers with a real choice, and each side's costs are worth walking through. Centralizing FFI management in one runtime layer, the way Wasm sandboxing does, buys consistency at the cost of flexibility. Distributing it across each storage or execution module, the way a multi-model architecture implies, buys the ability to optimize each boundary on its own terms, at the cost of consistency across the system. Neither choice makes the underlying mismatch go away. Each one just decides where its costs get paid, and who ends up responsible for managing them.
Why the remaining problems stay hard
None of this is converging toward a clean solution. The research directions aimed at recovering performance, operator fusion, JIT inlining, learned cost models, pull in one direction. The research directions aimed at recovering safety, Wasm sandboxing, process isolation, formal contracts, pull in the other. No approach on the table delivers both at once, at analytical scale, today.
Type system incompatibility has no general fix either. Every FFI layer draws its own line around what can cross, and that line is set by the semantic gap between the two type systems involved, not by how much engineering time gets thrown at it. Optimizer blindness has partial answers in GRACEFUL's learned cost estimation and QFusor's operator fusion, but both depend on the foreign function's behavior being observable or its code being accessible. That condition doesn't hold for closed-source libraries or runtimes sandboxed specifically to keep their internals hidden.
Agentic workloads add a requirement none of the existing designs were built for: machine-legible FFI contracts with full auditability. Retrofitting that onto an FFI built for human callers is not a small project.
What ties all of this together is a single collision, repeated at every layer of the system. FFI in an analytical engine is the site where two incompatible models of computation, declarative and procedural, meet directly, and every difficulty covered here, the planner's blindness, the broken pipeline, the type system's hard edges, the isolation trade-off, the correctness gap, the agentic pressure, the multi-model redistribution, follows from that same collision. Understanding FFI in analytical engines means understanding that it was never a bridge to begin with. It's the place where the two sides meet without ever fully agreeing on the terms.
Sources
- A Verified Foreign Function Interface between Coq and C
- Introduction to the PL/SQL Foreign Function Interface
- M2: An Analytic System with Specialized Storage Engines for Multi-Model Workloads
- Automating Database-Native Function Code Synthesis with LLMs
- ␣ ␣ Optimizing UDF Queries in SQL Data Engines Konstantinos Chasialis∗
- UDFBench: A new benchmark for UDF queries
- Foreign Function Interface (FFI)
- GRACEFUL: A Learned Cost Estimator For UDFs